AI Knowledge Base: What Actually Breaks AI Answers, and How to Fix It
Consider this scenario. A service team spends six months preparing its knowledge base for AI. Following the advice that is everywhere at the moment, they break a forty-page benefits handbook into dozens of small articles, apply a standard template to every one of them, strip out the jargon and convert the old PDFs into clean text.
Then an employee asks the new assistant how much parental leave she is entitled to, and it gives her the wrong answer.
Not because the articles were too long or badly formatted. The rewritten handbook said one thing, and a policy update sitting in SharePoint from earlier in the year said another, and nobody had noticed that the two disagreed. Six months of effort went into the part of the problem that no longer matters very much, while the part that does went untouched.
I think most AI knowledge base advice is out of date. That advice was written for the models of two or three years ago, which genuinely struggled with long documents and messy formatting, and it has kept circulating long after those constraints loosened. The result is that organizations start with an expensive rewrite, run out of patience before the rewrite finishes, and conclude that their knowledge was never ready for AI. What actually breaks AI answers today is different, and it is fixed by maintenance rather than by writing.
What is an AI knowledge base?
An AI knowledge base is the body of policies, procedures, troubleshooting steps and answers that an AI assistant draws on to respond to employees, along with the processes that keep that content accurate. The content usually spans several sources — the service desk's own articles, SharePoint, Confluence, policy documents, resolved tickets — rather than living in one place.
The difference from a traditional knowledge base is who reads it. A traditional knowledge base is searched by a person, who skims the results, notices when something looks out of date, and asks a colleague when the answer is unclear. An AI assistant does none of that on its own. It retrieves what looks relevant and answers from it, confidently, which means every contradiction and every gap in the underlying content eventually reaches an employee as a wrong answer.
What changed about how AI reads content
A good deal of the standard advice was sensible when it was written and is much less necessary now.
Current models handle long documents well. A forty-page handbook does not need to become forty separate articles for an assistant to find the paragraph about carry-forward rules, because retrieval has improved and models can hold far more context at once. Breaking content into small pieces can still help in places, but it is no longer a precondition.
PDFs and scans are readable. So are screenshots — in our own gap logs there is an employee who simply sent a photo of a blue error screen with the words "I ran into this issue on my laptop," and the system read the image as part of the question.
Varied writing styles are not the obstacle they were either, and internal shorthand is usually interpretable from context. Templates still help people write consistently, but they are not what stands between you and accurate answers.
None of that means content quality stopped mattering, only that the effort belongs somewhere else.
What actually breaks AI answers
Four things, and none of them is solved by rewriting.
Contradictions. Two sources disagree and the assistant has no way to know which one is current. The benefits handbook says one thing and a memo from March says another. The IT article describes last year's VPN client and the SharePoint page describes this year's. Organizations accumulate documentation in layers, and every layer that was never reconciled with the one beneath it is a wrong answer waiting to happen.
Staleness. An article was correct when it was written and quietly stopped being correct. The process changed, the tool was replaced, the approver left. Nothing in the article signals that, so the assistant repeats it with the same confidence it gives to everything else.
Gaps. The question has no answer anywhere in your content. A gap is the most common failure and the least visible one, because an employee who gets a vague response rarely reports it — they ask a colleague instead, and the gap stays open.
Applicability. The answer exists but does not say who it applies to. Parental leave depends on jurisdiction, tenure and employment class, and an article that states one entitlement without saying which employees it covers will be right for some people and wrong for everyone else.
Notice what these four have in common. None of them can be fixed by making an article shorter, clearer or better formatted, because each one is about the relationship between pieces of content, or between content and reality, rather than about any single article in isolation.
Why these are maintenance problems, not writing problems
A rewrite is an event: it happens once, produces a clean knowledge base on a particular day, and from the next morning onward that knowledge base starts drifting again. Policies change, systems get replaced, new questions appear that nobody anticipated, and old articles keep being served long after they stopped being true.
The organizations that keep accurate AI answers are not the ones that did the best rewrite, but the ones that can see, continuously, where their knowledge is failing, and have some way of fixing it faster than it decays. Seeing and fixing continuously is a maintenance discipline, and like every maintenance discipline it tends to lose to whatever is urgent this week unless something makes it easy.
So the useful question is not how to prepare your content for AI, but how you will know, next month, which answers have started going wrong.
How to see where your knowledge is failing
Declared interest: this is what we build, so read this section as a description of one approach rather than a neutral survey. The capabilities are worth asking for whichever product you use.
Knowledge gaps. Every question the assistant could not answer well is recorded as a gap, with the original question, who asked it and when. Each gap is also classified, and the classification matters more than it first appears. Some questions are simply out of scope — somebody asking the service desk how to bake a birthday cake. Some reveal insufficient knowledge, where the content does not cover the topic. And some are marked inaccurate, meaning an answer existed and it was wrong, which is the category that points most directly at a contradiction or a stale article.
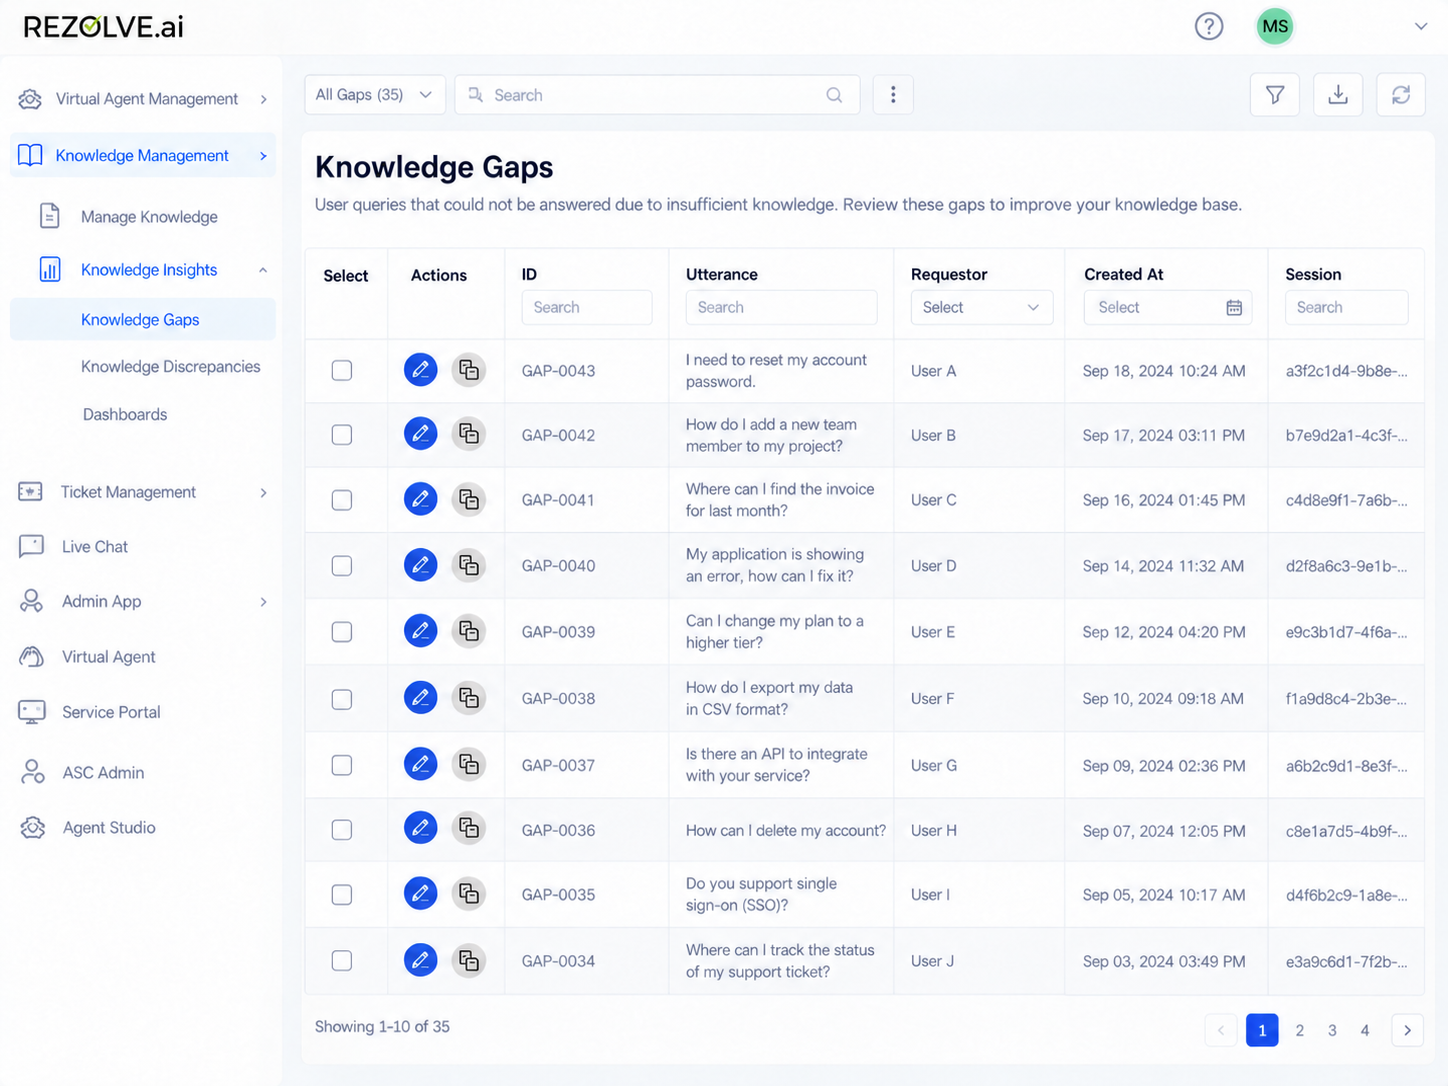 Figure 1. Knowledge Gaps shows the employee questions the system could not answer well, along with the type of gap identified.
Explainable AI for every gap. From any gap you can open the full reasoning behind the response: the question as the employee asked it, including any image they attached; how the system enriched it with context; which agent routed it; and which knowledge it retrieved. Seeing the reasoning turns "the assistant got it wrong" into something you can act on, because you can see whether the problem was missing content, the wrong article being retrieved, or a request that should have gone somewhere else entirely.
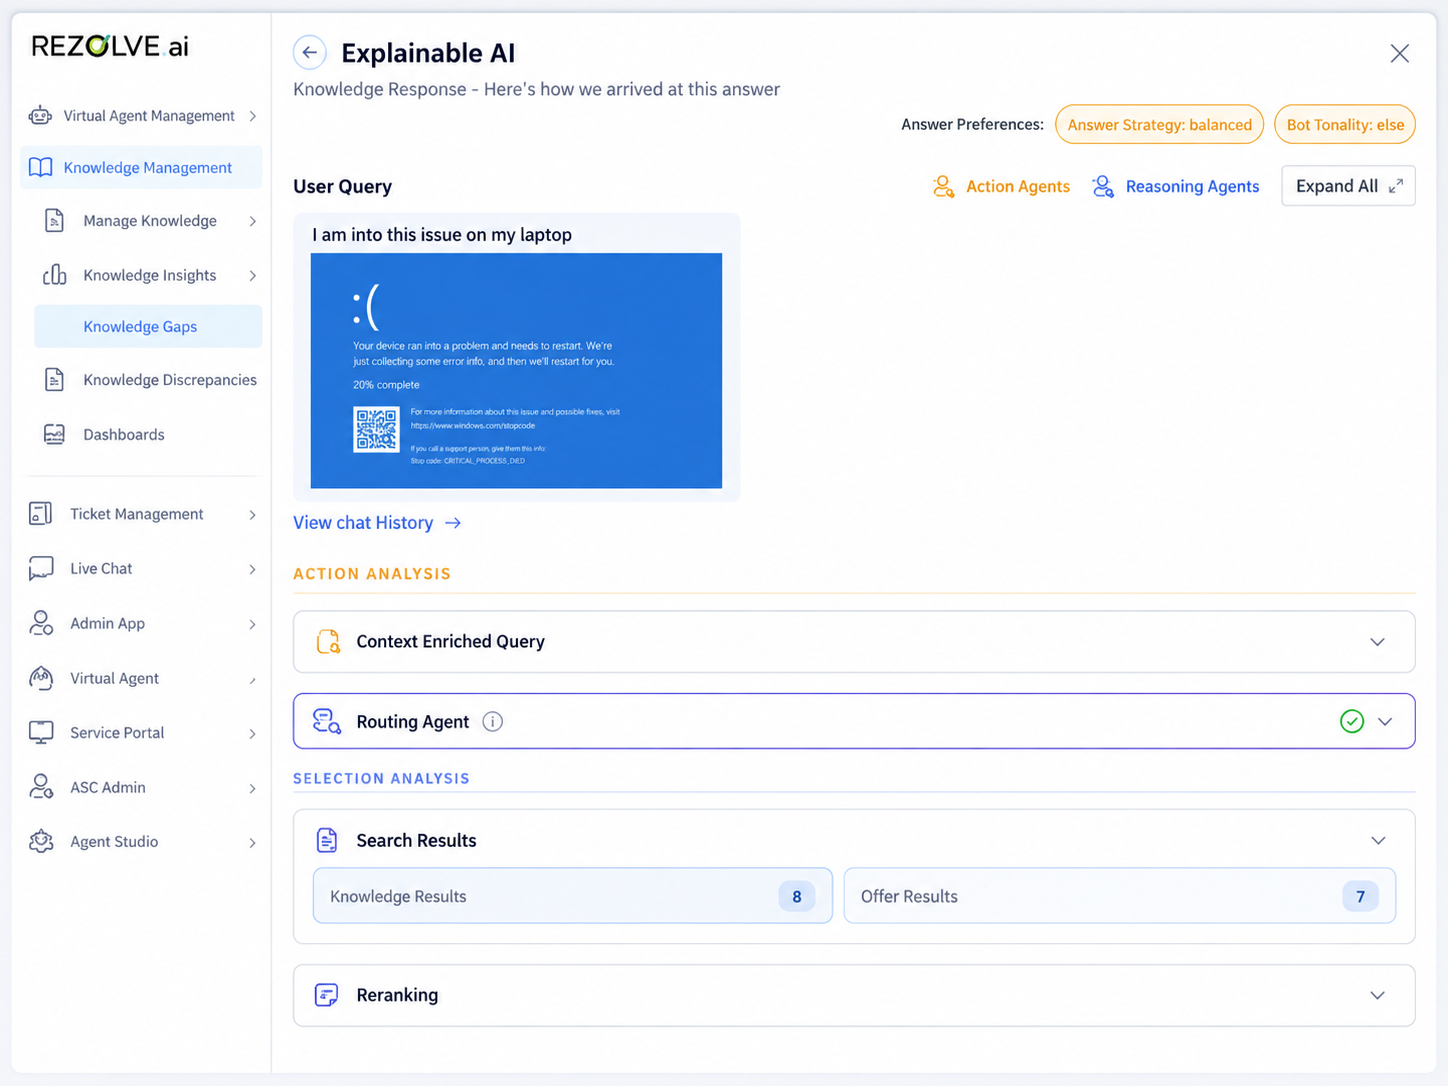 Figure 2. Explainable AI lets teams inspect how a response was produced, including the original query, contextual enrichment, routing and retrieved knowledge.
Knowledge discrepancies. Contradictions are flagged across sources — the service desk's own articles, SharePoint, scripted content — with the location in your knowledge hierarchy, the reason for the discrepancy and a confidence score. Discrepancy detection is the capability that would have caught the parental leave problem before any employee asked about it.
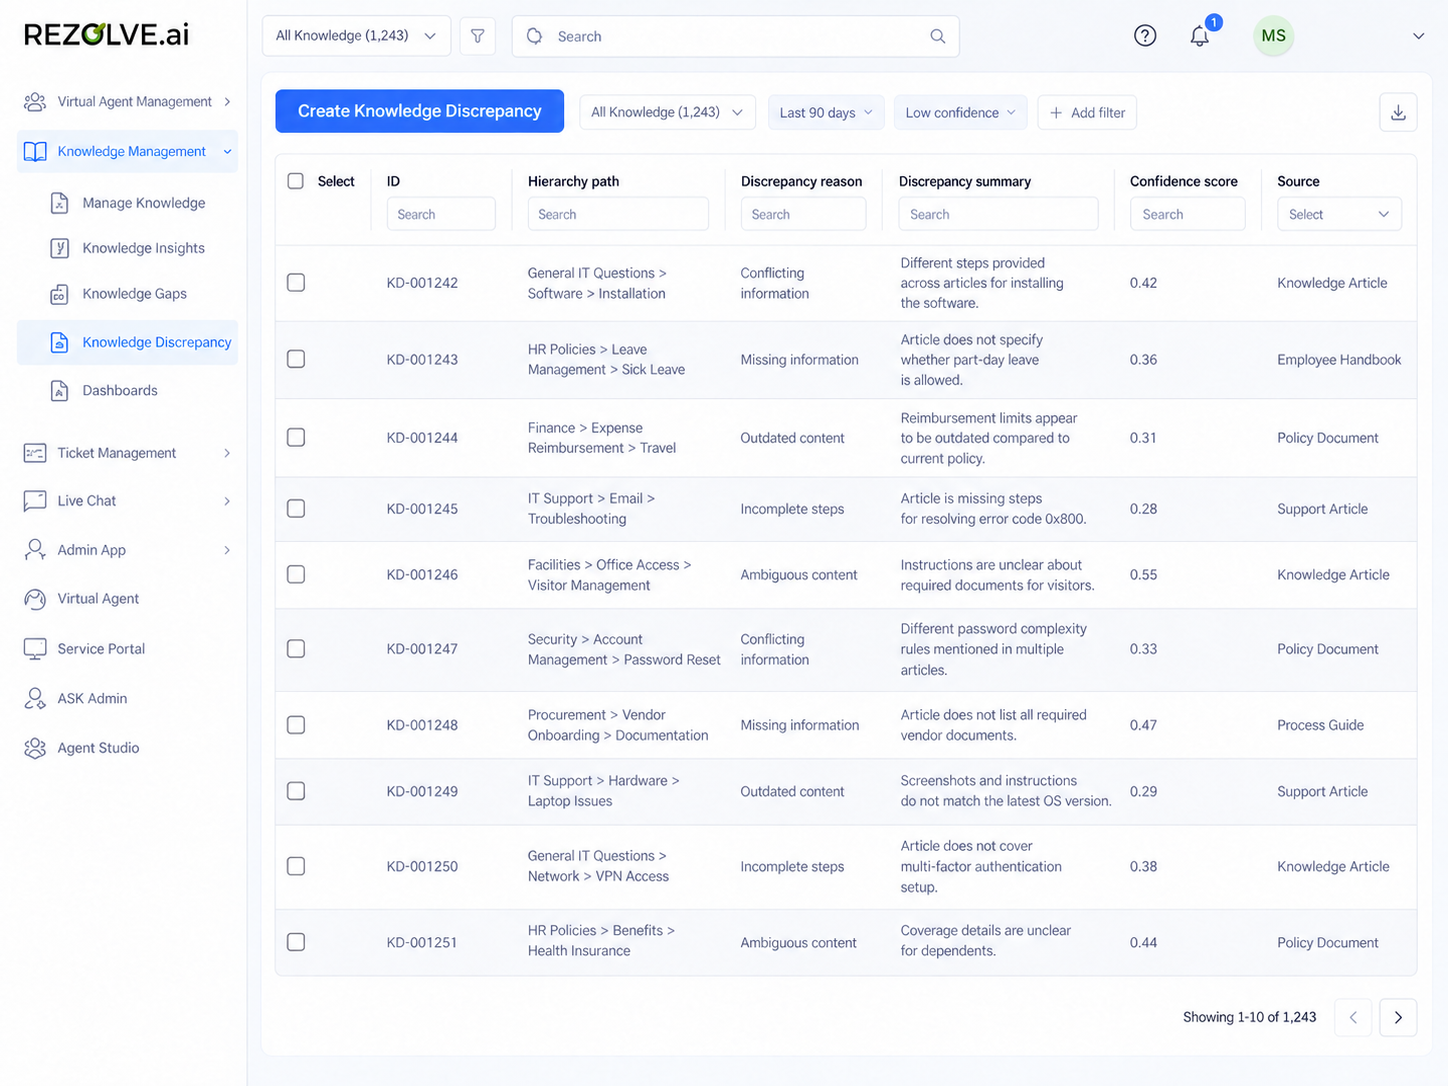 Figure 3. Knowledge Discrepancy highlights conflicting or incomplete knowledge across sources, helping teams identify what needs review before it becomes a wrong answer.
Knowledge dashboards. Gaps and discrepancies are shown against your knowledge hierarchy, so you can see where problems concentrate. If most of the gaps sit under software installation and most of the discrepancies sit under security policy, you know where to spend the next week rather than spreading effort evenly across everything.
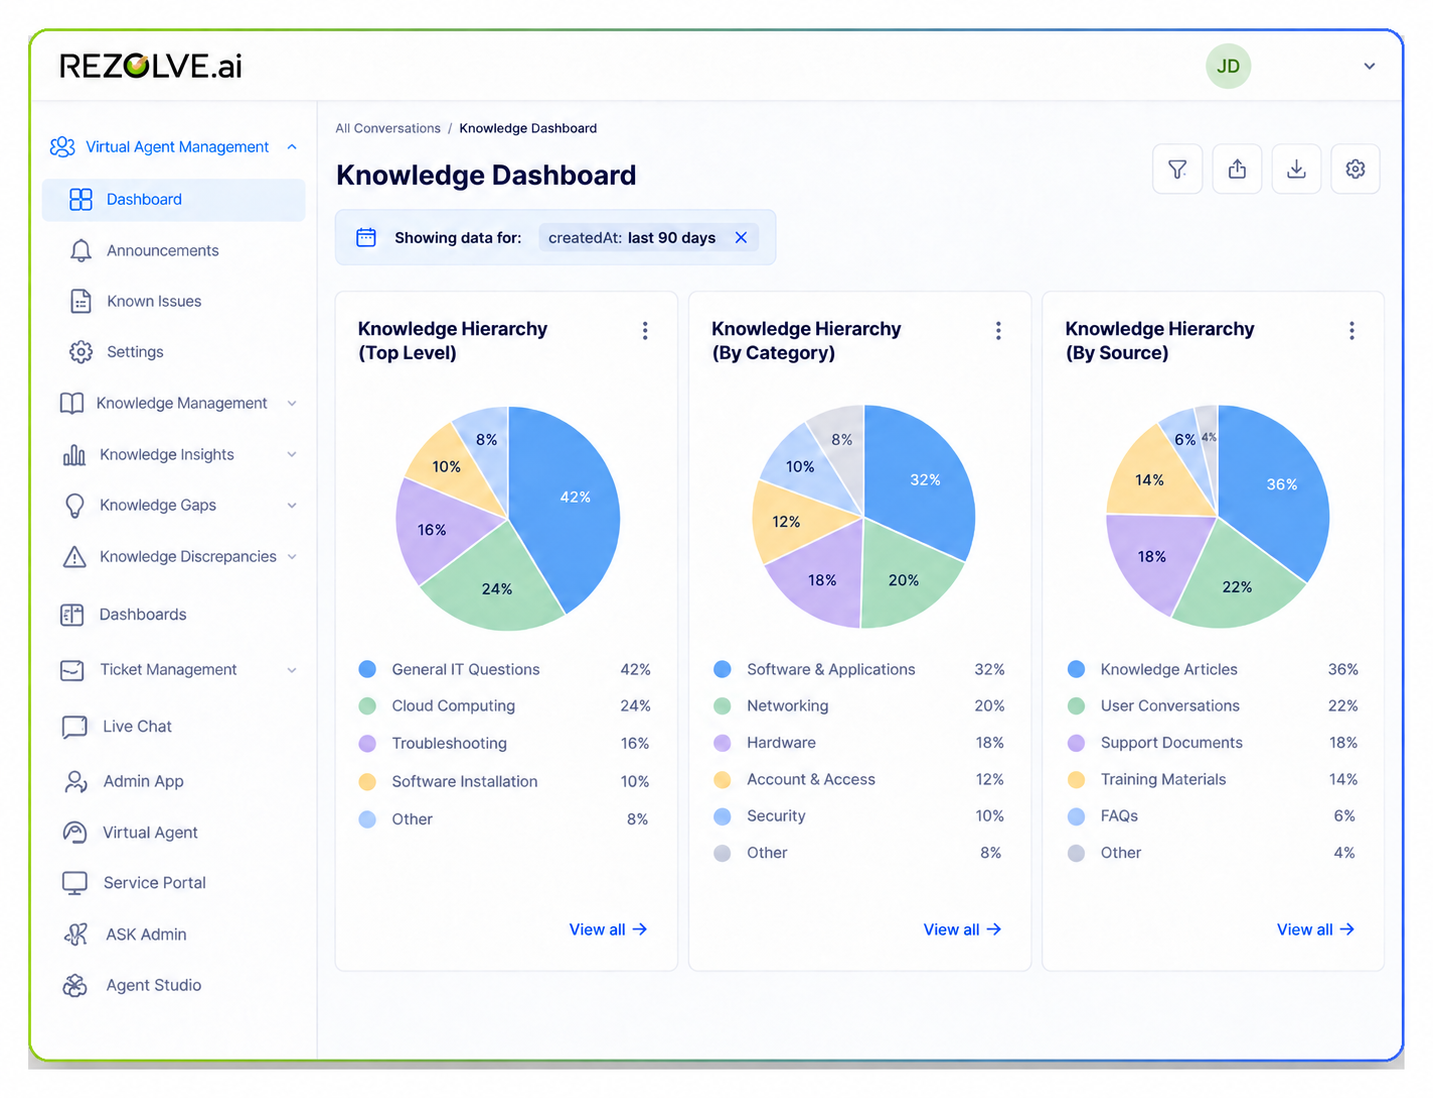 Figure 4. Knowledge Dashboard shows where gaps and issues cluster across the knowledge hierarchy, helping teams prioritize what to fix next.
How agents keep it maintained
Seeing the problems is half of it. The other half is having something fix them on a schedule people do not have to remember.
The Daily Knowledge Harvester is an agent that runs every day against the tickets resolved that day. For each resolved issue with a usable root cause or resolution note, it searches the existing knowledge base for an article covering the same problem. If one exists, it enriches that article with what was learned. If none exists, it creates a new one. The objective it is built around is specific: every distinct issue resolved that day should end up captured in exactly one published article, rather than scattered across duplicates.
That is the principle the knowledge management field has argued for years — capture knowledge at the moment of resolution, as a by-product of the work, rather than as a separate writing task nobody has time for. The difference is that it no longer depends on every analyst remembering to do it at the end of a long shift.
The harvester is built in Agent Studio, the same place customers build their own agents. So the maintenance your organization needs beyond this — a weekly review of articles nobody has opened in a year, a check that every policy article names the employee groups it covers — can be built the same way, with the same versioning, approvals and run history as any other agent.
What to ask before you buy an AI knowledge base product
Show me the questions it could not answer last month. If the product cannot produce that list, you will never know where your gaps are.
Show me a wrong answer and why it happened. You want to see the retrieved content and the reasoning, not just the response.
Show me where two of my sources disagree. Contradictions across systems are the most common cause of wrong answers and the hardest to find by hand.
Show me how a resolved ticket becomes an article. If the answer is that an analyst writes it, ask how often that actually happens.
Show me how an answer changes for a contractor in one country and a full-time employee in another. If both get the same article, applicability is not being handled.
Where this leaves you
Go back to the team that spent six months rewriting its knowledge base. The work was not wasted, since the content is clearer now. But the wrong parental leave answer came from two documents disagreeing, and no amount of rewriting would have found that, because the rewrite looked at each article on its own.
If you are about to start preparing your knowledge base for AI, I would spend less on the rewrite and more on visibility. Connect your sources, let real questions arrive, and look at what fails: the gaps, the contradictions, the answers that turned out to be wrong. Then put something in place that keeps closing them every day, because the knowledge base you have next quarter matters far more than the one you have on launch day.
If you want to see how Rezolve.ai turns existing knowledge into more accurate, explainable employee support, book a demo.
Last updated on September 23, 2026
Get summary with:
See the agentic service desk in action
Watch Rezolve.ai autonomously resolve real IT and HR tickets: governed, auditable, glass-box.