Service request management: how it differs from incidents, and what AI changes
"Outlook won't let me in" could be a service request or an incident, and the employee should never have to decide which. What separates the two, why the distinction still matters to the desk, and what changes when AI classifies and fulfills requests in the conversation.
"Outlook won't let me in."
That sentence arrives at a service desk thousands of times a year, and it could be two completely different things. If the employee's account is locked after too many password attempts, it is a service request: a routine, pre-approved piece of work with a known fix. If the mail server has gone down, it is an incident: an unplanned disruption that is probably affecting hundreds of other people at the same moment. One needs an unlock. The other needs the on-call engineer.
The employee has no idea which it is, and should not need to. Yet most service desks still ask them to decide, by making them pick between a "report a problem" form and a "request something" form before anybody has looked at what is actually wrong. The distinction between incidents and service requests matters a great deal to the people running the desk. It was never meant to be the employee's job.
I would argue that is the real story of service request management right now. The definitions have not changed. What has changed is who applies them, and when.
What is a service request?
A service request is a formal request from a user for something standard: access, information, a routine change, or an item from the service catalog. Resetting a password, unlocking an account, installing approved software, provisioning a laptop for a new hire, granting access to a shared folder. Nothing is broken. The user needs something, the organization has agreed in advance that they can have it, and the work follows a known path, often with an approval step.
Service request management is the practice of taking those requests in, routing them, getting them approved where approval is needed, fulfilling them, and closing them, ideally without anybody reinventing the process each time. In ITIL 4 terms it sits alongside incident management as a separate practice with its own goals and its own measures.
What is an incident?
An incident is an unplanned interruption to a service, or a reduction in its quality. The email server fails. An application throws errors for everyone in one region. The VPN stops accepting connections. Something that should be working is not, and the goal of incident management is to restore normal service as quickly as possible, then hand the underlying cause to problem management if it needs deeper investigation. We cover how those practices hand off to each other in incident, problem and change management compared.
Incident vs service request: the difference
| Service request | Incident | |
|---|---|---|
| What it is | A request for something standard | An unplanned interruption or degradation |
| Is anything broken? | No | Yes |
| Planned or unplanned | Planned and pre-approved | Unplanned |
| Typical trigger | "I need access," "I need a laptop," "I forgot my password" | "It's not working," "It's slow," "I'm getting an error" |
| Approval | Often required, and defined in advance | Rarely; speed of restoration comes first |
| How it is resolved | Fulfilled through a known, repeatable procedure | Diagnosed, then restored, sometimes with a workaround |
| Who is usually affected | One person | Often many people at once |
| What it is measured on | Time to fulfill, catalog coverage, requester satisfaction | Time to restore, impact, recurrence |
| Example | Unlock an account, install approved software | Mail server outage, application failure |
The row that matters most in practice is the one about who is affected. A service request is almost always about one person. An incident often is not, and the first ten reports of an outage look, individually, exactly like ten routine requests.
Why the distinction still matters to the desk
None of this is academic, because the two are handled differently for good reasons.
Priority. An incident affecting a whole department has to jump the queue in a way a software installation should not. If both arrive as generic tickets, the outage waits behind the installs.
Approval and control. Service requests carry pre-agreed approvals. Incidents sometimes need changes made quickly, under emergency change rules, and the audit trail has to show which was which.
Reporting. Mix the two and every metric goes wrong. Fulfillment time looks slow because it contains outages, restoration time looks fast because it contains password resets, and nobody can tell whether the catalog or the infrastructure needs attention.
Pattern detection. Ten locked-account requests in an hour from one office is not ten service requests. The pattern is far more likely a single incident with one cause, and a desk that only sees individual tickets finds out last.
Why it should stop being the employee's decision
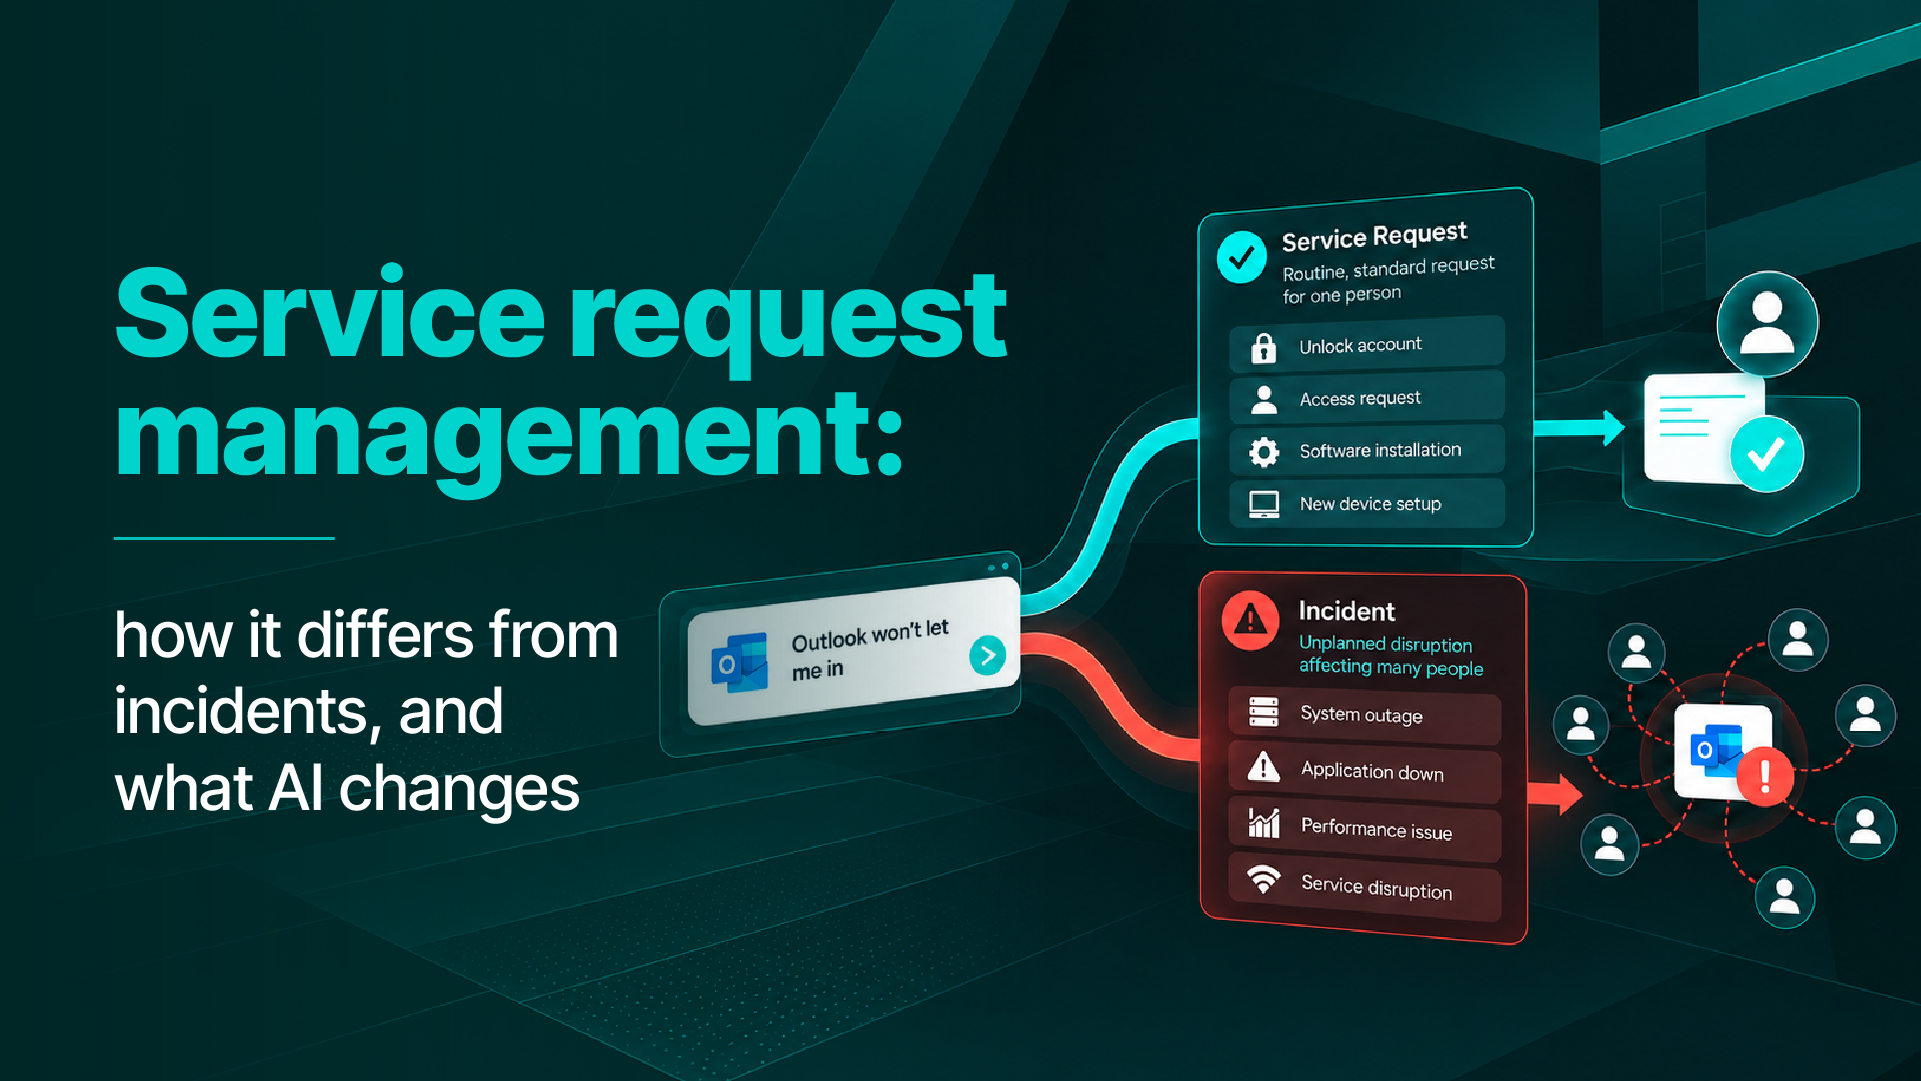
Figure 1. The same sentence can be a service request or an incident. The system decides from the directory and from other recent reports, so the employee never has to.
The traditional answer to all of that was to make the employee classify their own problem at the front door. Pick the right form, fill in the right category, and the desk will route it correctly.
The front-door form never worked well. People choose whichever form looks closest, or whichever one they used last time. The result is misrouted tickets, reclassification by the service desk after the fact, and employees who learn that raising anything takes too long and go to a colleague instead. A portal built around forms turns the ITIL distinction into a usability problem.
The better arrangement is for the employee to describe what is happening, in their own words, wherever they already are, and for the system to do the classification. "Outlook won't let me in" gets checked against the directory: if the account is locked, it is a service request and the unlock can happen in the same conversation. If the mail service is degraded and forty other people have said something similar in the last ten minutes, it is an incident, and the employee is told that it is known and being worked on rather than sent to raise a ticket nobody needs.
The distinction is applied more consistently this way, not less, because it is applied by something looking at the directory and the pattern of other reports rather than by a person guessing between two forms.
What changes when service requests get fulfilled rather than routed
Classification at the front door is half of it. The larger change is what happens next.
In most service request management today, a well-classified request still becomes a ticket, waits in a queue, and gets fulfilled by a technician following a procedure. For the standard requests that make up most of the volume, the procedure is already known, the approval rules are already written down, and the only thing missing is something to carry it out.
Carrying out that work is the part AI now does. A password reset, an account unlock, a software installation from the approved catalog, a new-hire provisioning flow: each can be verified, approved where the rules require it, executed, and closed in the conversation where it was asked for. The request never becomes a ticket for a person to pick up, and it is the reason L0 and L1 support elimination has become a baseline expectation rather than an ambition.
The effect is easiest to see outside office hours. Black Angus Steakhouse moved routine requests and endpoint troubleshooting to an AI assistant and cut the share of support calls arriving after hours from 90 percent to 10 percent, because restaurant staff working evenings no longer had to wait for the desk to open to get a standard request done.
Incidents change too, though less dramatically. The AI does not fix a failed server. What it does is recognize from the pattern of reports that one is failing, tell affected employees what is known, attach the context to the incident record, and keep the desk from drowning in duplicate tickets while the engineers work.
What should stay with people
A few things are worth being deliberate about, because getting them wrong is how autonomous fulfillment loses trust.
Anything that needs judgment. Access to sensitive systems, exceptions to policy, and requests that fall outside the catalog should go to a person, with the context already gathered. Automation is for the requests where the answer is already agreed.
Approvals that exist for a reason. If a request requires a manager's approval today, the AI should route it to the manager, not skip it. The gain is in removing the waiting, not the control.
Identity before action. Nothing sensitive should happen on an identity that has not been confirmed. A reset requested from a verified session is one thing; the same request from an unrecognized phone number is another.
Integration with what you already run. Most organizations have an ITSM system of record they are not going to replace this year, whether that is ServiceNow, Jira Service Management or something else. Fulfillment has to write back to it, so the record stays complete and the audit trail stays in one place.
Privacy. Service requests routinely touch employee data. Whatever does the fulfilling has to respect the same access controls, retention rules and regulatory obligations, including GDPR and HIPAA where they apply, as the people it is taking work from.
How Rezolve.ai handles requests and incidents
This is what we build, so read the next three paragraphs with that interest in mind.
Rezolve.ai puts the front door where employees already work. Sidekick takes the request in Microsoft Teams, Slack, email, the web, mobile or on the phone, works out whether it is a request or a report of something broken, and for standard requests carries the work out in the same conversation: resetting the password, unlocking the account, provisioning the software, starting the onboarding flow. Approvals are routed to the people who own them, and every action is recorded on the ITSM system of record, including incident, request, change and joiner-mover-leaver, or written back to ServiceNow, Freshservice or Jira if that is what you already run.
The full flow — configuration, detection, declaration, war room and closure.
Across deployments, 60 to 80 percent of common requests are resolved autonomously, and the rest reach a person already analyzed and summarized. The Automation Catalog ships with ready-to-run flows for the requests most desks see every day, and anything specific to your organization can be described in plain language and drafted in Agent Studio.
Back to "Outlook won't let me in." In a desk that works this way, the employee who typed it never sees a form. If the account was locked, it is unlocked before they finish their coffee. If the mail server is down, they are told so in the same reply, and their message is attached to an incident that the desk already knew about. Either way the distinction was made correctly, and it was made by the system rather than by the person least equipped to make it.
Learn more about how Sidekick resolves requests before they become tickets.
Last updated on October 12, 2026
Get summary with:
See the agentic service desk in action
Watch Rezolve.ai autonomously resolve real IT and HR tickets: governed, auditable, glass-box.
Frequently asked questions
Is a password reset an incident or a service request?
A password reset is a service request. Nothing is broken; the user needs a standard, pre-approved piece of work done. It can become part of an incident if many people are locked out at once from the same cause, for example after a directory change, in which case the individual requests are symptoms of one incident.
Can a service request turn into an incident?
Yes. A request can reveal that something is broken, such as an access request that fails because the underlying application is down. When that happens the record should be reclassified or linked to an incident so priority, reporting and the audit trail reflect what actually occurred.
What is the difference between service request management and request fulfillment?
Request fulfillment is the older ITIL v3 name for the process of carrying out service requests. ITIL 4 uses service request management for the broader practice, which includes intake, routing, approval, fulfillment and closure, along with maintaining the catalog of requests the organization has agreed to support.
What should a service catalog include?
The standard requests your organization has agreed to fulfill, each with a defined procedure, the approvals it requires, who is entitled to request it, and the expected time to fulfill. A catalog is most useful when it is written around what employees actually ask for rather than around how the IT organization is structured.
Which service request metrics matter most?
Time to fulfill, the share of requests fulfilled without a person, first-time fulfillment without rework, and requester satisfaction. Keep them separate from incident metrics, because combining the two distorts both: fulfillment looks slow when outages are mixed in, and restoration looks fast when routine requests are counted.